Chapter 6Governance as architecture
This book treats governance as a load-bearing structural layer in any production agentic system. Validators, policy gates, approval workflows, and oversight determine whether an agent’s outputs can reach systems of record and under what conditions.
This chapter develops governance as a first-class architectural concern. It defines the governance layer, names its components, places it relative to the bounding layer (Chapter 5) and the agent loop (Chapter 2), and treats the operational patterns (human-in-the-loop, validator chains, policy gates, risk-based escalation, critic-executor splits, and rollback) as architectural elements with explicit contracts.
Most treatments of governance in the agentic literature (Gulli 2025 on Safety Patterns; the CSIRO catalog on Guardrails; Andrew Ng’s brief discussion of human-in-the-loop) treat governance as a category of patterns. Here governance is the layer through which everything the agent emits must pass before it has effect.
The categorical mistake
The most common categorical mistake in agentic systems is to treat governance as a feature added to a working agent. The architecture diagram has the agent in the center; governance is a box on the side labeled “Safety,” connected by an arrow. The arrow suggests that governance is consulted; the diagram does not require that governance is traversed.
This is wrong in the same way that “Authentication” as a feature added to a working application is wrong. Authentication is a structural property of the request lifecycle, enforced before anything else: an unauthenticated request never reaches business logic. Governance is the same kind of property of the action lifecycle: an action that has not passed it does not have effect; it is rejected or escalated at the boundary.
Governance sits on every path from model output to effect. Before a tool call executes, the gateway validates and gates the proposed action, with approval where policy requires it. Responses pass through validation and sanitization before they reach the user. Memory updates undergo consistency and policy checks before persistence.
This reframing has a cost: more architectural surface area, more code, more configuration. The cost is justified; relying on the agent to behave correctly is not a substitute. The remainder of the chapter develops the structure.
Why prompt-based governance fails
Governance cannot live in the prompt. A large fraction of agentic systems in 2024–2026 attempted exactly that (“do not do X,” “always validate Y,” “ask the user before Z” in the system prompt), and the approach fails for three reasons that are now well-documented in the security literature.
First, the model is not bound by prompts. A system prompt expresses intent; it does not enforce constraints. The model can ignore a system-prompt instruction when its training, the user prompt, or attacker-controlled content in retrieval or tool responses pushes in another direction.
Second, prompt-based governance is opaque to audit. A regulator or an internal reviewer asking “what prevents the agent from doing X” cannot inspect a prompt and conclude anything. Prompts are advisory; their enforcement is statistical at best.
Third, prompt-based governance is brittle across model updates. A prompt that worked with one model version may fail with the next. The team finds out at incident time. Architectural enforcement is stable across model upgrades; prompt-based enforcement is not.
The position this chapter takes is unconditional: prompts express preferences and orientation, while deterministic infrastructure outside the model enforces policy and constraints.
Components of the governance layer
The governance layer has five architectural elements in the action pipeline and two cross-cutting patterns developed after the diagram. Each has an explicit role and contract. Together they form the enforced structure between the agent’s outputs and the world. Canonical sources (Gulli 2025 on Safety Patterns and Human-in-the-Loop; Anthropic’s Building Effective Agents on evaluator-optimizer and guardrails) cover these elements in framework-specific detail.
The academic literature converged over 2025–2026 on the need for runtime governance. MI9 (2025) on runtime governance frameworks and governance-by-design (Dux et al., 2026) make that argument directly. SAGA (2025) supplies the adjacent security architecture, including agent identity, access control, and inter-agent communication, that the governance layer depends on; see Chapter 21. This chapter integrates that shared position with bounded autonomy, the trace, and the harness. Once the five pipeline elements are named, it develops the temporal placement of human oversight.
1. Schema validators
Pre-action enforcement of structural correctness on every output that the agent emits, tool call arguments, structured responses, plan documents, memory updates. A schema validator either accepts or rejects; rejection is observable to the agent and triggers retry, replan, or abort according to policy.
Schema validators are deterministic. Their behavior is fully described by the schema. Schemas are versioned: the schemas in production are the schemas in the trace, and an action that does not conform to its schema does not happen.
Every interface between the agent and the rest of the system carries a schema. Tool calls have schemas; outputs to channels have schemas; memory writes have schemas; inter-agent messages have schemas. Schema-less interfaces are gaps in the governance layer; they are the easiest gaps for attackers and for accidental misbehavior to exploit.
Schema design is itself an architectural skill. A schema that is too permissive admits malformed actions; a schema that is too restrictive forces the agent to work around it (often by smuggling content through free-text fields). The right schemas are just constrained enough to catch malformed actions while allowing the legitimate variation the agent needs. Iterate on schemas as the system runs; tighten them when permissive fields turn out to be misused; loosen them when restrictions force workarounds.
When to use. Always, at every interface between agent and world. Schema validation has the lowest cost and the highest payoff of any governance pattern.
When not to use. There is no agent-to-world interface where omitting schema validation is safe; it is the baseline for every deployment.
Related patterns. Policy gate (stricter), constraint-guided reasoning (Chapter 4), trace-driven retry.
2. Policy gates
Rule-based enforcement of operational and compliance policy. Policy gates check actions and outputs against domain rules: “no transactions over X without approval,” “no PII in outputs to this channel,” “no actions on accounts flagged for legal hold,” “no use of model versions older than N,” “no skill loading outside business hours.” Policy gates are typically expressed in a structured form (a rule engine, OPA, a small DSL) so that policy can be audited and changed without redeploying the agent.
Every policy that applies to an action is enforced by a gate. A prompt may communicate the policy to the agent, but it cannot guarantee compliance. The gate is the system of record: it receives the proposed action and its context (session identity, current state, recent history), then returns allow, deny, or escalate. Its behavior is testable.
The relationship between policy and schemas is hierarchical: schemas check that the action is structurally valid; policy checks that the action is substantively acceptable. A perfectly schema-valid refund for $50,000 may violate a policy that limits agent-initiated refunds to $500. The schema gate accepts the action; the policy gate denies it (or routes it to approval).
Policy expression should be declarative and reviewable. A team should be able to ask “what are the current policies?” and receive an answer that is shorter and clearer than the codebase. If the policy is buried in 100 lines of imperative code, it is hard to audit and easy to drift; if it is 50 rules in a rule engine, it is auditable and the drift is visible.
One concrete concern policy gates enforce is data-loss prevention: the agent must not emit secrets, credentials, or personal data. Policy gates handle this by integrating deterministic DLP scanners, Microsoft Presidio, named-entity recognizers, or regex pipelines for secret patterns, rather than asking the model to redact itself. The scan is a deterministic check over the output; the policy decides what happens on a match (deny, redact, or escalate). Running such a gate over output bound for a user creates a tension with token-by-token streaming: a gate cannot judge a response it has not yet seen in full, which the architecture resolves at the interface, through chunked buffering or optimistic rollback, rather than by sacrificing either streaming or the gate (Chapter 13).
When to use. For any rule that must hold absolutely: tax compliance, KYC checks, data handling, privilege boundaries, channel restrictions.
When not to use. For soft preferences. Tone and style belong in the prompt or a critic, not a policy gate.
Related patterns. Schema validator, risk-based escalation, audit trail.
3. Approval gates (human-in-the-loop)
Routing of high-risk or irreversible actions to a human reviewer before commit. Approval gates have specific contracts:
-
Routing rules, which actions require approval, by which role.
-
Context, what the reviewer sees (the proposed action, the reasoning trace, the diff between current state and post-action state).
-
Timeout, what happens if no decision is made within a deadline.
The architectural pitfall is to treat human-in-the-loop as “send an email.” Approval gates are stateful workflow components, with their own queue, observability, and audit trail. The reviewer’s decision is part of the trace and is replayed alongside the agent’s actions.
Concord (Chapter 17) shows the selectivity concretely: it routes propose_commit to a human gate while its sandboxed read_file, run_tests, and write_file actions pass through bounded autonomy untouched. The gate sits on the one irreversible action, submitting code for a human to merge, not on every step the agent takes.
An exploratory field study of seventeen developers using software agents (Dhanorkar, Passi, and Vorvoreanu, 2026; Chapter 21), a small, largely single-employer sample, finds that oversight work concentrates at configuration and post hoc review while co-planning and in-flight monitoring stay thin relative to what runaway trajectories require. That matches the failure shape this book argues for: teams that bound well but never review the plan before execution, and never interrupt a drifting run, pay in tool spend and irreversible milestones before a per-action gate fires.
Plan approval gate. The plan approval gate reviews a trajectory before execution. The agent produces a structured plan covering tools, data scope, milestones, estimated iterations, and spend. Execution begins only after a reviewer approves it. The contract specifies what the reviewer sees (the plan, the goal artifact, the bounding envelope in effect), the available decisions (approve, reject, modify, request replan), and what re-triggers review (any replan that changes tools, data scope, or irreversible milestones).
Its benefit exceeds its review cost on long-horizon tasks, high aggregate spend, and workflows with irreversible milestones because it catches plan corruption and runaway trajectories before a tool call is spent. The Plan-Execute pattern (Chapter 4) names this gate; the long-running-analysis vignette (Chapter 16) treats it as load-bearing; Chapter 14’s dry-run API is the platform-level analog. One review of the trajectory can also replace dozens of per-action approvals on steps the plan already authorized.
Approval gates also have a fatigue dynamic. If every action requires approval, reviewers stop reading and start clicking. The approvals become noise. The next genuine incident slides through. The architectural answer is risk-based escalation (next section): approval gates are used selectively, on actions that genuinely warrant human judgment, and the rest pass through bounded autonomy without human intervention.
The reviewer’s experience matters. An approval queue that presents the action without context (the agent’s reasoning trace, the proposed diff, the risk score, the precedent cases) cannot be reviewed meaningfully. Design the approval UI as part of the system, not as an afterthought (Chapter 13). The reviewer is a load-bearing component of the architecture.
As of mid-2026, human oversight is no longer only an architectural argument for a large class of EU deployments: Regulation (EU) 2024/1689 (the EU AI Act) requires high-risk AI systems to be designed for effective human oversight, including the ability to intervene in or interrupt operation (Article 14), with conformity obligations staged on a rolling calendar subject to deferral. What does not change is the architectural substance: compliance is made of inspectable runtime mechanisms (the approval gate, the stop control (Chapter 13), the trace), not the prompt-based “oversight” this chapter rejects as unauditable. This is not legal advice; it is the observation that the governance layer is the substrate regulators are mandating (Chapter 21).
When to use. Always for irreversible actions above a risk threshold; for sensitive content, customer communications, financial actions, and any first-of-kind operation a new agent has not been observed to perform reliably. Use the plan approval gate when the task is long-horizon, high aggregate spend, or Plan-Execute shaped (Chapter 4). Begin with broad approval on a new capability and narrow it as reliability is demonstrated.
When not to use. As a generic safety net. Approval on every action collapses into fatigue and rubber-stamping; reserve it for actions that genuinely warrant human judgment.
Related patterns. Risk-based escalation, policy gate, reversibility envelope (Chapter 5).
4. Risk-based escalation
Dynamic routing of an action through a stricter or weaker governance path depending on a risk score. The score may come from the agent’s self-reported confidence (with care, self-reports are not always reliable), from a separate risk-scoring model, from the action’s classification (read vs. write, dollar amount, target system criticality), or from a combination.
Risk-based escalation is the mechanism by which low-risk actions proceed automatically and high-risk actions are approved. The risk score itself is auditable: changing the score’s behavior is a controlled change, not a prompt tweak.
The thresholds matter. Set them too high and most actions auto-approve, including ones that should not; set them too low and the approval queue overflows with low-risk noise. The right thresholds are derived from data, the actual distribution of action risk in the system’s traffic, not from a designer’s intuition. Operate on the percentiles: route the riskiest decile to approval, the next decile to a lighter review, the rest to autonomous execution. Tune as the system evolves.
Risk scoring has its own failure modes. A score that is too smooth across action classes blurs the genuine cliff between low- and high-risk; a score that is too sharp produces classifier-style misroutes (an action just under the threshold passes autonomously when it should not). Calibrate on incident data. Chapter 12 develops the greenfield bootstrap when incident data does not yet exist: actions that turned out to be problematic should have had risk scores above the escalation threshold; if they did not, the score is mis-calibrated.
The deterministic nature of governance comes under pressure when risk scoring uses a probabilistic component, a classifier, or an LLM judge. The score remains an input to fixed routing logic. For example, if risk_score >= 0. applies the same rule to every score. The model may estimate how risky an action is; deterministic code decides whether enforcement applies.
Prefer narrow, specialized evaluators to general LLMs wherever possible. A DLP scanner can detect PII, a fast local classifier can classify intent or toxicity, and a regex pipeline can find secrets. These components are cheaper, faster, more testable, and harder to manipulate than a general model asked to judge.
When to use. For systems with a wide spread of action risk, an agent that mostly answers questions but occasionally provisions infrastructure.
When not to use. For systems where action risk is uniform; a purely customer-facing chatbot has roughly one risk level, and escalation adds complexity without benefit.
Related patterns. Approval gate, policy gate, reversibility envelope (Chapter 5).
5. Rollback and recovery
Compensating mechanisms for actions that turn out to be wrong, even after passing all the prior gates. Rollback is its own discipline:
-
For reversible actions, rollback is a corresponding inverse action (delete what was created, refund what was charged, retract what was sent).
-
For partially reversible actions, rollback is a compensating workflow (apologize, notify, mitigate).
-
For irreversible actions, a true rollback is impossible by definition, but a compensating transaction is usually possible. If an agent emails 80,000 customers, the message cannot be unsent. The defined response can include an apology email, an account flag, and a suppression entry. That response belongs in the action’s contract alongside the requirement for prior approval (the reversibility envelope, Chapter 5).
Rollback components are deterministic. They are tested explicitly. They are exercised in chaos testing (Chapter 12). A system whose rollback paths exist on paper but have never been exercised has no rollback in practice: the first time the path is needed, it does not work.
The saga pattern from microservices literature applies directly: each action in a sequence has a defined compensation; partial failures trigger compensation in reverse order. Compensation is part of the action’s contract, defined at the same time as the action itself, not added later as remediation.
When to use. For all reversible and partially reversible actions, and to define the compensating transaction for permitted irreversible ones.
When not to use. As a substitute for prevention on truly irreversible actions; for those, the reversibility envelope (Chapter 5) must prevent the action without prior approval.
Related patterns. Reversibility envelope, approval gate, audit log.
The temporal placement of oversight
Human oversight has three temporal placements. Before delegation, the bounding specification and action surface of Chapter 5 fix limits, tool allowlists, and data scope before the loop runs. At plan time, the plan approval gate lets a reviewer approve the trajectory before any consequential action executes.
In flight, approval gates and risk-based escalation work with the steering and interruption controls of Chapter 13. These controls let a reviewer intervene while the loop runs.
Post hoc review and rollback close the loop after effects occur. They are necessary, but they cannot substitute for the earlier placements on runaway-trajectory failures, and the architectural response at each placement is a named gate, not more prompts.
The architectural diagram
Putting these together with the bounding layer from Chapter 5:
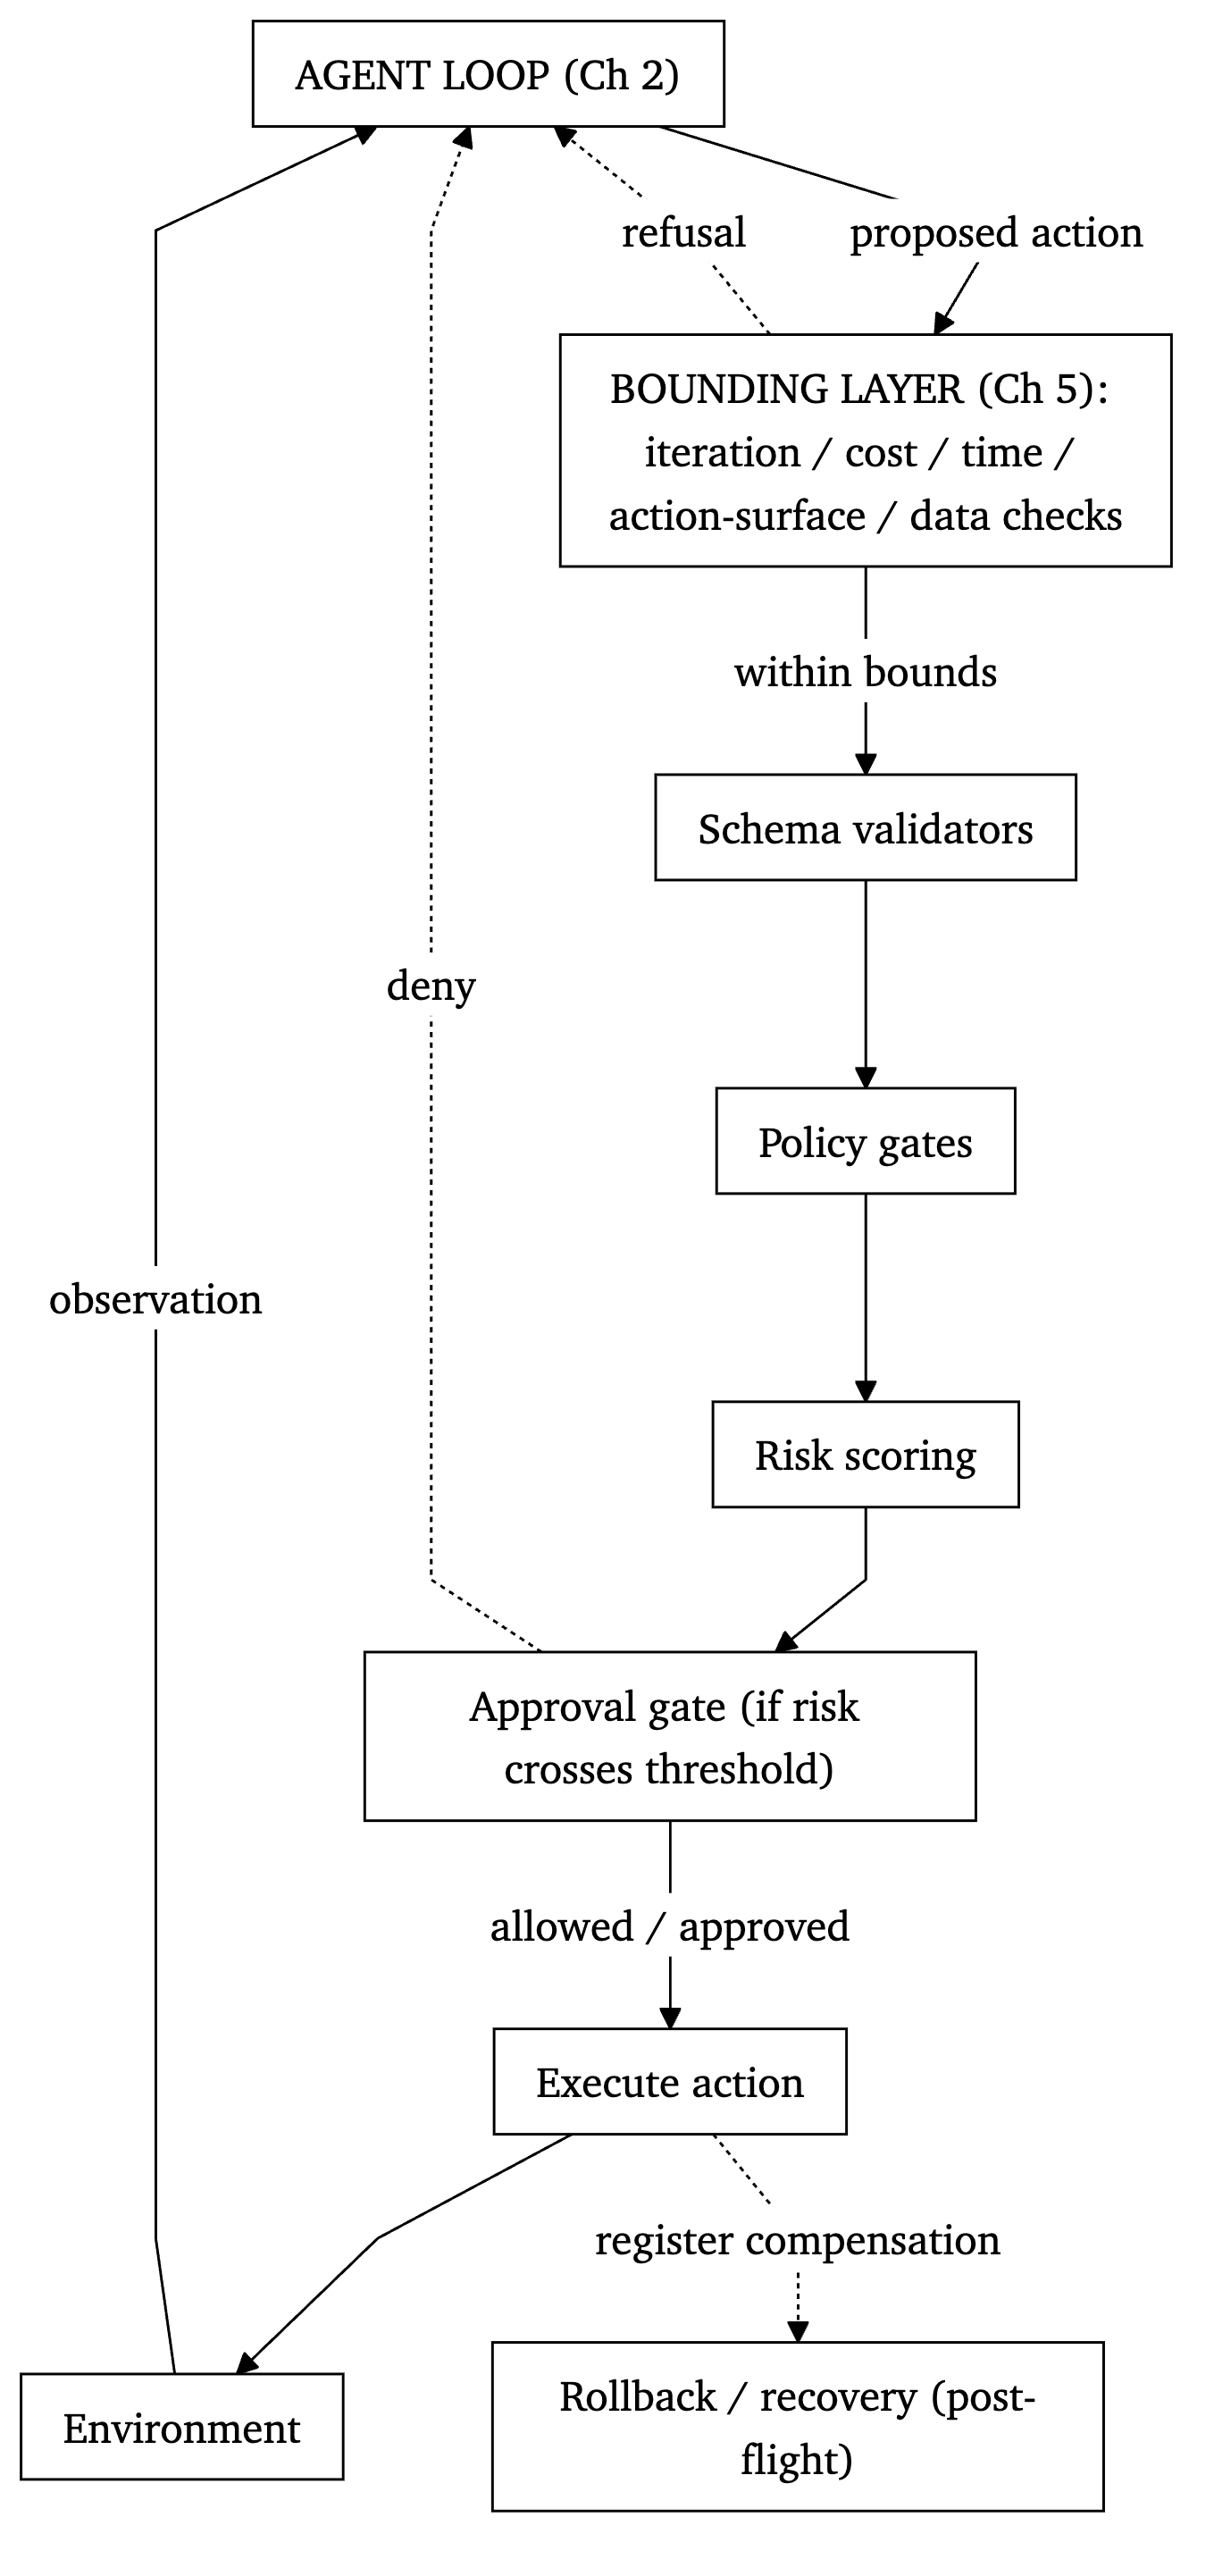
The action lifecycle is the order in which a proposed action passes through the layers:
-
Bounding layer checks iteration, cost, time, action surface, data scope.
-
Governance layer validates schema, applies policy gates, computes risk score.
-
If risk score warrants, governance layer routes through an approval gate.
-
Rollback path is registered for partially or fully reversible actions.
Every step is logged and replayable, and the routing at each step is deterministic: the decision to allow, deny, or escalate follows fixed rules, even when an input such as a risk score is probabilistic. The order of checks matters too: bounds before governance, since a bound failure is cheaper to surface, and within governance, schemas first (cheap, deterministic), then policy (more expensive, still deterministic), then risk scoring (potentially a model call), then approval (a human). Cheaper checks first; an action that fails one does not consume the rest. Schema validation, policy, risk scoring, and approval are pre-flight gates that can block the action; rollback and recovery are post-flight mitigation that compensates after it has run. The Saga pattern is that post-execution half made systematic.
Chapter 17 walks the governance pipeline end-to-end with pseudocode for each stage in the Concord worked example.
Two cross-cutting governance patterns
The five elements above sit in the action pipeline. Two further patterns cut across it: one adds an independent evaluator before an action commits, the other makes the whole layer auditable after the fact.
Critic-executor split
Intent. Separate the generation of an action from its evaluation by an independent component.
Architectural commitments. The critic is a separate component, typically a different model, a different prompt, or both. It may see test results, a stricter rubric, or another perspective unavailable to the executor. Its verdict has a defined effect: blocking, requiring revision, or annotating the trace.
As with risk scoring, the critic may be probabilistic. The rule that acts on its verdict remains deterministic.
When to use. When the failure modes of the executor are well-characterized and the critic can be designed to catch them. Code generation with test execution as the critic. Drafting with a stricter style validator. Plan generation with a feasibility check. Anthropic’s evaluator-optimizer workflow is the canonical realization.
When not to use. Where the critic is just another copy of the executor with a prompt asking it to “check the answer.” That construction adds latency and cost without independent signal. The critic must have independent failure modes from the executor; otherwise both fail the same way and the pattern provides no defense.
Related patterns. Reflection (Ch 4), evaluator-optimizer (Anthropic), debate (Ch 4).
Observability and audit
Intent. Make every reasoning step, tool call, memory access, policy decision, and approval event observable, attributable, and replayable.
Architectural commitments. Structured traces (Chapter 12). Per-action attribution to the agent and session. Immutable audit log of governance events. Replay capability for incident response. Trace retention for governance events is typically longer than for routine operational traces: compliance windows often dictate years rather than weeks.
When to use. Always. There is no agentic system in production for which trace discipline is optional.
When not to use. Never. (Trace overhead is real but small relative to model and tool cost; the savings from skipping it are dwarfed by the costs of debugging without it.)
Related patterns. Every other governance pattern relies on trace discipline to be auditable.
Composing the governance patterns
The patterns above are not alternatives; they compose. A typical action passes through several of them in sequence. A coding agent’s request to commit changes might:
-
Pass the schema validator (the commit operation has the expected arguments and signs).
-
Pass the policy gate (the files touched are not in a protected set; the commit message follows convention; the diff size is below a threshold).
-
Receive a risk score (low if the agent has touched only its own working files, higher if it has touched shared modules, highest if it has touched security-sensitive paths).
-
Route to an approval gate if the risk score crosses a threshold (a human reviews the diff and the test results).
-
Register a rollback path (the prior branch state is recorded so the commit can be reverted if needed).
Each layer catches a different class of failure (structural, rule, contextual, judgmental, residual), and defense in depth is the explicit architectural pattern that combines them.
Governance and the skills layer
Skills (Chapter 10) introduce a runtime-extension mechanism that complicates governance. A skill is procedural knowledge an agent loads on demand; if the skill itself contains instructions that bypass governance (an attacker-controlled skill, a poorly-audited community skill), the governance layer must remain effective despite the skill’s content.
The constraint, developed in Chapter 10, is that skills do not change the governance layer. A skill can declare what it needs (tools, data scope, approval level); the governance layer evaluates the declaration and either admits the skill with the appropriate constraints or refuses it. Skills are subordinate to governance, not a way around it.
This is the architectural answer to the “lethal trifecta” class of vulnerabilities: untrusted content (a skill, a retrieval document, a tool response) combined with sensitive data access and external action capability. Governance enforced at the action and output layers, not at the prompt layer, defends against this class. A skill that tells the agent to invoke a forbidden tool produces a refused action at the bounding layer; a skill that tells the agent to send sensitive data to an external endpoint produces a refused action at the policy gate. The skill is read; its instructions have no effect that the architecture does not permit.
This reframing matters because the alternative, detecting the attack itself, is not reliably achievable. A prompt injection rides inside the very content the model must read to do its work; to the model, the poisoned instruction and the legitimate text are the same kind of thing, and no deterministic scanner separates them with the reliability the rest of the system demands. Treating injection as a filtering problem invites precisely the prompt-based thinking this chapter rejects, one layer down. The architecture therefore does not try to catch the semantic attack; it makes the attack inert by denying the agent any consequential action to be tricked into. Break the trifecta by removing any one of its three legs from the shared context: untrusted content, sensitive data access, or external action capability. A successful injection then reaches nothing. The defense blocks consequential action even when the injection succeeds.
Governance and multi-agent systems
Multi-agent systems multiply the surface area of governance. Each agent’s actions must pass through governance; inter-agent communication must also pass through governance (because one agent can be the channel by which another agent’s prompt is injected with adversarial content). An attacker who cannot inject directly into a sensitive agent may be able to inject through a less-protected agent that passes content to the sensitive one.
The architectural pattern is to centralize the governance layer even when the agents are distributed. A single governance service, used by all agents, enforces the same validators, policies, gates, and escalations regardless of which agent submitted the action. Centralized governance:
-
Allows policy changes to take effect across the fleet immediately.
-
Avoids the failure mode where one agent has weaker governance than another and becomes the channel for the abuse of the rest.
-
Enables fleet-wide observability of governance events (Chapter 18).
Per-agent customization lives in configuration over a single governance layer, not in separate implementations. The governance layer is shared infrastructure; the policies, schemas, and thresholds it enforces vary per agent through declarative configuration.
Governance anti-patterns
Five anti-patterns recur in production:
Prompt-based governance. “We told the agent in the system prompt not to do X.” The system prompt is a recommendation, not a constraint. The agent will, under the right circumstances, do X. Governance must be enforced by deterministic code outside the agent.
Single-validator governance. “We have a schema validator.” Schemas catch malformed actions; they do not catch policy-violating actions. A perfectly schema-valid action can still be a refund larger than the agent is authorized to issue. Defense in depth: validators, gates, approvals.
Approval-fatigue governance. “Everything requires human approval.” The reviewers stop reading. Approvals become rubber-stamping. Use risk-based escalation to route approvals to the few actions that warrant them; the rest pass through bounded autonomy.
Governance behind feature flags. “We can disable governance for development.” A feature flag that bypasses the governance layer can accidentally remain enabled in production. Keep the layer active in every environment and vary the policy according to the environment.
Reactive governance. “We add a policy when an incident shows we need one.” This is the right trigger for adding policy; it should not be the only trigger. The governance layer is reviewed proactively as the system evolves, new tools, new data flows, new agents, new failure modes cataloged in the literature, not only when an incident lands.
The cost and return of governance
Governance has a cost. The case that it is justified rests on three structural facts:
-
The cost of governance is borne per action: tens of milliseconds and a small fraction of model cost for the deterministic checks this chapter describes.
-
The cost of an incident is borne per incident (rarely, but at scale when it occurs): engineering time, remediation, customer-trust loss, and possibly regulatory exposure.
-
A small per-action cost averts a rare but large per-incident cost, with positive expected return whenever the system has any meaningful blast radius.
The structure is the same as for transaction logging or input sanitization: a small per-operation cost that averts a rare large per-incident cost. This is a reasoned accounting, not a published measurement. For systems with small blast radius (a single-user demo, a research notebook), lighter governance is acceptable; the mistake is to carry it into production where the blast radius is real.
A worked cost model
The preface names the reader who needs this argument most: the architect who must defend the line to leadership. That defense must account for returns as well as costs.
The model below illustrates the tradeoff with parameters drawn from published sources. It does not report measurements from a named deployment.
The incident avoided. In Moffatt v. Air Canada (Chapter 5; see Chapter 21), a chatbot misstated bereavement-fare policy and the tribunal held the airline liable for roughly C$812 in damages and fees. Remediation beyond the award is heavier (legal review, policy correction, retraining, customer handling), conservatively sixteen cross-functional hours. At a loaded labor rate near $95/hr (U.S. Bureau of Labor Statistics median for software developers, May 2024, with a 1.5× total-compensation load), that is roughly $1,500 in labor; add one conservatively attributable churned account at $1,200 of annual contract value, setting softer reputation cost aside, and the incident totals roughly $3,500 in hard costs. At enterprise scale the IBM-Ponemon Cost of a Data Breach Report (2024) puts the average breach above $4.8M, a different magnitude, the same ratio shape. The composite iteration failure in Chapter 5 (seventeen sequential refunds before detection) makes the same argument at larger scale.
The governance overhead that would have prevented it. A policy gate on fare and refund representations, or an output validator at display (Chapter 13), catches the misstatement before the customer relies on it; an iteration limit and refund policy gate contain the runaway-refund variant. The per-action overhead is small: schema validation is sub-millisecond and free; a policy-gate evaluation is 1–5 milliseconds; a risk-score call is a few milliseconds with a narrow classifier, or a single cheap classification of a few hundred tokens where it uses a model call. Across a 25-tool-call support session, the overhead is well under a cent of model cost and under 100 milliseconds of latency; across a fleet of a thousand sessions a day, single-digit dollars and imperceptible latency.
The tradeoff. A per-action overhead measured in milliseconds and fractions of a cent, paid on every action, averts a $3,500 incident whenever one occurs. At a conservative one incident per quarter, the fleet’s runtime overhead is on the order of a few hundred dollars a quarter against an incident cost an order of magnitude larger, before the customer-trust tail leadership actually fears. The ratio improves with the incident rate. The one cost the model understates is the engineering time to build the pipeline, a one-time amortized investment that prevents incidents for the life of the system; where the ratio is an order of magnitude or better the case is made, and where it is not, the lighter-governance calculation above genuinely applies.
Governance as a cultural commitment
The commitment described in this chapter is also a cultural one. The team that operates the system has to internalize the discipline:
-
Engineers who add a new tool also add the schema, the policy entries, and the risk-scoring contribution.
-
Engineers who change a policy do so through the policy-as-code pipeline, with review, not by editing a prompt.
-
On-call engineers know how to read governance events in the trace and how to respond when an alert indicates governance has caught something.
-
Reviewers know how to assess an approval-queue item, what to look at, what to flag, when to escalate.
-
The team treats governance events as signal: a sudden change in deny rates is investigated rather than silenced.
Without the cultural commitment, the architecture erodes. New tools ship without schemas. Policies drift behind the system. Approval queues fill with low-context items and reviewers stop reading. The architecture is in place but no longer effective. The strongest defense against this erosion is to make governance discipline visible (dashboards showing deny rates, schema coverage, approval-queue depth, and time-to-decision) and to treat regressions in the discipline as defects.
Summary
Governance is the architectural layer that turns a bounded agent into a system component. It is composed of schema validators, policy gates, approval gates (including the plan approval gate where Plan-Execute applies), risk-based escalation, and rollback paths, with observability and audit running through all of them. Oversight is placed before delegation (Chapter 5), at plan time, and in flight (Chapter 13), not only at per-action gates. It sits between the agent and the world; every action, every output, every memory update passes through it before it has any effect.
Governance enforcement is deterministic: fixed rules decide whether to allow, deny, or escalate, even when a probabilistic evaluator such as a risk scorer supplies an input. The decision does not rest on the agent’s judgment. Governance is also load-bearing: the system is designed around it, not patched with it. Chapter 7 takes up memory architecture, the layer that gives the agent state and that governance also has to mediate.